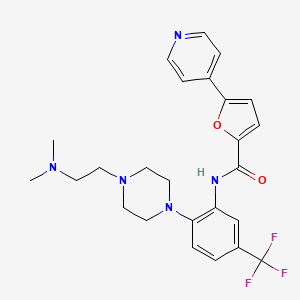
SPHINX scaffold, 3
Product document request
Request a Representative COA
No file is available for instant download. Submit this short request and our team will review the applicable document for this product.
Request submitted
描述
化合物“SPHINX 支架,3”是一种用于各种科学研究应用的合成化学支架。支架在药物化学和药物设计中至关重要,因为它们提供了核心结构,可以在其上连接不同的官能团以创建各种生物活性化合物。SPHINX 支架,3,特别地由于其独特的结构特性和化学合成的多功能性而受到关注。
属性
分子式 |
C25H28F3N5O2 |
|---|---|
分子量 |
487.5 g/mol |
IUPAC 名称 |
N-[2-[4-[2-(dimethylamino)ethyl]piperazin-1-yl]-5-(trifluoromethyl)phenyl]-5-pyridin-4-ylfuran-2-carboxamide |
InChI |
InChI=1S/C25H28F3N5O2/c1-31(2)11-12-32-13-15-33(16-14-32)21-4-3-19(25(26,27)28)17-20(21)30-24(34)23-6-5-22(35-23)18-7-9-29-10-8-18/h3-10,17H,11-16H2,1-2H3,(H,30,34) |
InChI 键 |
ALLIMXLDTJFWHR-UHFFFAOYSA-N |
规范 SMILES |
CN(C)CCN1CCN(CC1)C2=C(C=C(C=C2)C(F)(F)F)NC(=O)C3=CC=C(O3)C4=CC=NC=C4 |
产品来源 |
United States |
准备方法
合成路线和反应条件: SPHINX 支架,3 的制备涉及几种合成路线。 一种常见的方法包括使用计算机辅助设计 (CAD) 软件来设计支架结构,然后生成标准三角语言 (STL) 文件并对 3D 对象进行切片以进行打印 。然后使用 3D 打印工艺来创建支架,并对其结构特征进行精确控制。
工业生产方法: 在工业环境中,SPHINX 支架,3 的生产通常涉及先进的增材制造技术,例如快速成型。 这些方法允许高效且可扩展地生产支架,具有高精度和可重复性 。
化学反应分析
反应类型: SPHINX 支架,3 经历各种化学反应,包括氧化、还原和取代反应。这些反应对于修饰支架以实现所需的特性和功能至关重要。
常用试剂和条件: 涉及 SPHINX 支架,3 的反应中使用的常见试剂包括烷基胺、缺电子烯烃和膦催化剂 。反应条件通常涉及控制温度和压力以确保高产率和选择性。
形成的主要产物: 涉及 SPHINX 支架,3 的反应形成的主要产物包括四取代环戊烯基骨架和其他结构复杂的化合物。 这些产物通常用作生物活性分子合成的构建块 。
科学研究应用
SPHINX 支架,3 具有广泛的科学研究应用。在化学领域,它用作合成各种生物活性化合物的核心结构。 在生物学领域,它用作组织工程和再生医学的支架,为细胞生长和分化提供框架 。在医学领域,它用于药物设计和开发,特别是在创建新的治疗剂方面。 此外,SPHINX 支架,3 还应用于工业应用,例如先进材料和纳米技术的生产 。
作用机制
SPHINX 支架,3 的作用机制涉及其作为多个蛋白质对接的分子中枢的作用,为信号级联组织有效的功能单元 。支架可以发生构象变化,影响其依赖性信号通路,从而影响细胞反应。 涉及的分子靶点和通路包括丝裂原活化蛋白激酶 (MAPK) 信号通路以及细胞中的其他关键调节通路 。
相似化合物的比较
与其他类似化合物的比较: SPHINX 支架,3 由于其结构特性和化学合成的多功能性而独一无二。 与其他支架相比,它提供更高的精度和对其结构特征的控制,使其适合各种应用 。
类似化合物的列表: 与 SPHINX 支架,3 相似的化合物包括其他用于药物化学和药物设计的合成支架,例如 Murcko 框架和一级支架 。这些化合物具有相似的结构特征,但在其具体应用和功能方面有所不同。
常见问题
Q. What methodological advantages does SPHINX offer over traditional composition- and alignment-based binning algorithms in metagenomic sequencing?
SPHINX combines the speed of composition-based methods (e.g., k-mer frequency analysis) with the accuracy of alignment-based approaches (e.g., homology searches) by using a hybrid framework. It employs a two-stage process: (1) rapid compositional pre-binning to reduce dataset complexity, followed by (2) targeted alignment using curated marker genes for taxonomic assignment. This reduces computational time by ~40% compared to pure alignment-based tools while maintaining >90% accuracy in simulated datasets .
Q. How should researchers preprocess metagenomic data to optimize SPHINX’s performance in taxonomic binning?
Key steps include:
- Sequence quality control : Trim low-quality reads (Q-score <20) and remove host-derived sequences.
- Read-length normalization : SPHINX performs best with sequences ≥1,000 bp; shorter reads may require error correction or merging.
- Dataset partitioning : Split large datasets into smaller batches (e.g., 10,000 sequences/batch) to leverage parallel processing. Reference databases should be updated to include recent additions to NCBI RefSeq to avoid misclassification of novel taxa .
Advanced Research Questions
Q. How can researchers design experiments to validate SPHINX’s binning accuracy when handling highly divergent microbial genomes?
- Simulated datasets : Use tools like CAMISIM to generate synthetic metagenomes with known ground-truth compositions, spiking in sequences from underrepresented taxa (e.g., archaeal extremophiles).
- Cross-validation : Compare SPHINX’s output with alignment-based tools (e.g., MetaPhlAn) and compositional classifiers (e.g., Kraken2). Discrepancies should be resolved via PCR-amplified marker gene sequencing (e.g., 16S rRNA).
- Parameter tuning : Adjust k-mer size (default: 32) and alignment stringency thresholds for datasets with high GC-content or horizontal gene transfer events .
Q. If SPHINX and alignment-based tools yield conflicting taxonomic assignments, what analytical approaches reconcile these discrepancies?
Contradictions often arise from:
- Short sequences : Alignment-based methods fail with fragmented data, while SPHINX’s compositional stage may over-classify.
- Evolutionary divergence : Novel taxa lacking reference genomes may be misassigned. Resolution strategies :
- Apply a consensus pipeline: Retain only assignments supported by ≥2 algorithms.
- Use phylogenetic placement tools (e.g., pplacer) to contextualize ambiguous sequences within reference trees.
- Perform functional annotation (e.g., COG, KEGG) to infer taxonomy from metabolic pathways .
Q. What parameters in SPHINX most significantly impact binning specificity in low-abundance species detection, and how should they be calibrated?
- K-mer size : Smaller k-mers (e.g., 24–28) improve sensitivity for rare species but increase false positives.
- Abundance thresholds : Default settings may exclude taxa contributing <0.1% to the community; lower the threshold to 0.01% for extremophilic environments.
- Marker gene selection : Curate custom marker databases for niche-specific studies (e.g., marine hydrothermal vents) to reduce misclassification .
Methodological Integration
Q. How can SPHINX be incorporated into the PICO framework for structuring clinical metagenomics studies?
- Population (P) : Define the host cohort (e.g., immunocompromised patients).
- Intervention (I) : Apply SPHINX to characterize gut microbiome shifts post-antibiotic treatment.
- Comparison (C) : Compare against conventional diagnostics (e.g., culturomics).
- Outcome (O) : Measure diagnostic accuracy in identifying pathogen dominance (e.g., Clostridioides difficile). This framework ensures alignment between SPHINX’s technical capabilities and clinical research goals .
Q. What strategies ensure comprehensive inclusion of SPHINX-processed data in systematic reviews of metagenomic analysis tools?
- Reference backtracking : Trace citations from foundational papers (e.g., SPHINX’s 2020 validation study).
- Researcher verification : Contact authors of studies using hybrid binning methods to confirm SPHINX’s usage.
- Journal hand-searching : Review recent issues of Bioinformatics and Microbiome for updates or comparative studies. Document inclusion/exclusion criteria (e.g., ≥80% accuracy in benchmark datasets) to maintain reproducibility .
Data Management & Validation
Q. How should researchers handle false-positive taxonomic assignments generated by SPHINX in large-scale environmental studies?
- Post-binning filtering : Exclude assignments with confidence scores <0.7.
- Negative controls : Include mock communities (e.g., ZymoBIOMICS) to quantify false-positive rates.
- Machine learning correction : Train classifiers on SPHINX’s output using tools like SHOGUN to refine predictions .
Q. What metrics are critical for reporting SPHINX’s performance in method validation sections?
- Accuracy : Percentage of correctly binned sequences in simulated datasets.
- Specificity : Proportion of non-target sequences correctly excluded.
- Runtime : Wall-clock time vs. dataset size (e.g., minutes per 10,000 sequences).
- Scalability : Maximum dataset size tested without performance degradation .
Tables for Reference
| Parameter | Default Value | Optimization Use-Case |
|---|---|---|
| K-mer size | 32 | Rare species detection: 24–28 |
| Alignment score cutoff | 80 | High-divergence taxa: 70 |
| Abundance threshold | 0.1% | Extreme environments: 0.01% |
| Validation Step | Tool/Resource | Purpose |
|---|---|---|
| Ground-truth simulation | CAMISIM | Generate synthetic metagenomes |
| Consensus classification | MetaPhlAn, Kraken2 | Cross-algorithm validation |
| Phylogenetic placement | pplacer | Resolve ambiguous assignments |
Featured Recommendations
| Most viewed |


|
|
|---|---|---|
| Most popular with customers |
|
体外研究产品的免责声明和信息
请注意,BenchChem 上展示的所有文章和产品信息仅供信息参考。 BenchChem 上可购买的产品专为体外研究设计,这些研究在生物体外进行。体外研究,源自拉丁语 "in glass",涉及在受控实验室环境中使用细胞或组织进行的实验。重要的是要注意,这些产品没有被归类为药物或药品,他们没有得到 FDA 的批准,用于预防、治疗或治愈任何医疗状况、疾病或疾病。我们必须强调,将这些产品以任何形式引入人类或动物的身体都是法律严格禁止的。遵守这些指南对确保研究和实验的法律和道德标准的符合性至关重要。
