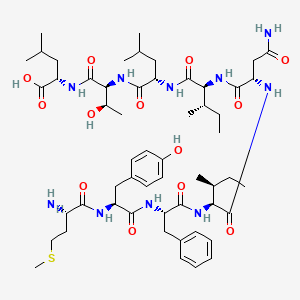
MHC binding peptide
Product document request
Request a Representative COA
No file is available for instant download. Submit this short request and our team will review the applicable document for this product.
Request submitted
描述
属性
分子式 |
C55H86N10O13S |
|---|---|
分子量 |
1127.4 g/mol |
IUPAC 名称 |
(2S)-2-[[(2S,3R)-2-[[(2S)-2-[[(2S,3S)-2-[[(2S)-4-amino-2-[[(2S,3S)-2-[[(2S)-2-[[(2S)-2-[[(2S)-2-amino-4-methylsulfanylbutanoyl]amino]-3-(4-hydroxyphenyl)propanoyl]amino]-3-phenylpropanoyl]amino]-3-methylpentanoyl]amino]-4-oxobutanoyl]amino]-3-methylpentanoyl]amino]-4-methylpentanoyl]amino]-3-hydroxybutanoyl]amino]-4-methylpentanoic acid |
InChI |
InChI=1S/C55H86N10O13S/c1-11-31(7)44(52(74)60-38(24-29(3)4)49(71)65-46(33(9)66)54(76)62-42(55(77)78)25-30(5)6)64-51(73)41(28-43(57)68)61-53(75)45(32(8)12-2)63-50(72)40(26-34-16-14-13-15-17-34)59-48(70)39(27-35-18-20-36(67)21-19-35)58-47(69)37(56)22-23-79-10/h13-21,29-33,37-42,44-46,66-67H,11-12,22-28,56H2,1-10H3,(H2,57,68)(H,58,69)(H,59,70)(H,60,74)(H,61,75)(H,62,76)(H,63,72)(H,64,73)(H,65,71)(H,77,78)/t31-,32-,33+,37-,38-,39-,40-,41-,42-,44-,45-,46-/m0/s1 |
InChI 键 |
LZOIGVDSAMDBIO-LXWJMTKESA-N |
手性 SMILES |
CC[C@H](C)[C@@H](C(=O)N[C@@H](CC(=O)N)C(=O)N[C@@H]([C@@H](C)CC)C(=O)N[C@@H](CC(C)C)C(=O)N[C@@H]([C@@H](C)O)C(=O)N[C@@H](CC(C)C)C(=O)O)NC(=O)[C@H](CC1=CC=CC=C1)NC(=O)[C@H](CC2=CC=C(C=C2)O)NC(=O)[C@H](CCSC)N |
规范 SMILES |
CCC(C)C(C(=O)NC(CC(=O)N)C(=O)NC(C(C)CC)C(=O)NC(CC(C)C)C(=O)NC(C(C)O)C(=O)NC(CC(C)C)C(=O)O)NC(=O)C(CC1=CC=CC=C1)NC(=O)C(CC2=CC=C(C=C2)O)NC(=O)C(CCSC)N |
产品来源 |
United States |
准备方法
合成路线和反应条件
主要组织相容性复合体结合肽的合成通常涉及固相肽合成。该方法允许将氨基酸依次添加到锚定在固体树脂上的生长肽链上。该过程包括以下步骤:
偶联: 第一个氨基酸连接到树脂。
脱保护: 去除氨基酸上的保护基团。
下一个氨基酸的偶联: 下一个氨基酸被添加到生长的链中。
重复: 步骤2和3重复,直到获得所需的肽序列。
裂解: 肽从树脂上裂解并纯化.
工业生产方法
主要组织相容性复合体结合肽的工业生产通常涉及自动肽合成仪,该合成仪可以生产大量高纯度的肽。这些合成仪使用与固相肽合成相同的原理,但针对大规模生产进行了优化 .
化学反应分析
反应类型
主要组织相容性复合体结合肽可以发生各种化学反应,包括:
氧化: 含有半胱氨酸残基的肽可以通过氧化形成二硫键。
还原: 二硫键可以还原为游离硫醇。
取代: 氨基酸残基可以被取代以改变肽的性质.
常用试剂和条件
氧化: 过氧化氢或碘可以用来氧化半胱氨酸残基。
还原: 二硫苏糖醇或β-巯基乙醇可以用来还原二硫键。
主要产物
科学研究应用
主要组织相容性复合体结合肽在科学研究中具有多种应用:
免疫学: 它们被用来研究T细胞反应和开发疫苗。
癌症研究: 这些肽被用于开发癌症免疫疗法。
传染病: 它们被用来识别和表征病原体的表位。
自身免疫性疾病: 对这些肽的研究有助于了解自身免疫性疾病的机制和开发靶向疗法
作用机制
主要组织相容性复合体结合肽通过与抗原呈递细胞表面上的主要组织相容性复合体分子结合来发挥作用。这种结合具有高度特异性,取决于肽的氨基酸序列和主要组织相容性复合体分子的结合沟。一旦结合,肽-主要组织相容性复合体复合物就会被T细胞受体识别,从而导致T细胞活化和免疫反应 .
相似化合物的比较
类似化合物
非主要组织相容性复合体结合肽: 这些肽不结合到主要组织相容性复合体分子上,因此在抗原呈递中不发挥作用。
主要组织相容性复合体I类结合肽: 这些肽特异性地结合到主要组织相容性复合体I类分子上,并被细胞毒性T细胞识别。
主要组织相容性复合体II类结合肽: 这些肽特异性地结合到主要组织相容性复合体II类分子上,并被辅助性T细胞识别
独特性
主要组织相容性复合体结合肽在结合到主要组织相容性复合体分子上并将抗原呈递给T细胞方面是独一无二的。这种特性对于激活适应性免疫系统和发展针对病原体和肿瘤的免疫反应至关重要 .
常见问题
Q. How do researchers select appropriate benchmark datasets for validating MHC-peptide binding prediction algorithms?
Benchmark datasets should prioritize allele diversity, quantitative binding measurements (e.g., IC₅₀ values), and standardized experimental conditions. Established datasets like Pan-I and Pan-II (for MHC-I and MHC-II, respectively) are curated to evaluate pan-specific methods, ensuring coverage of rare alleles and low-data scenarios . Databases such as IEDB and SYFPEITHI provide binding affinities across MHC supertypes, while Table 2 and 3 in Toward more accurate pan-specific MHC-peptide binding prediction list critical resources for training and validation .
Q. What experimental parameters are critical for optimizing peptide-MHC binding assays in vitro?
Key parameters include:
- Refolding additives : Glycerol improves MHC class II stability .
- pH and temperature : Optimized per MHC heterodimer (e.g., pH 5.0–6.0 for MHC-II) .
- Peptide length : Truncation of α/β chains in MHC-II requires empirical tuning . High-throughput scintillation proximity assays (SPA) and gel filtration with radiolabeled peptides enhance quantitative accuracy .
Q. How do basic pan-specific prediction methods differ from allele-specific approaches?
Pan-specific methods leverage shared binding motifs across MHC supertypes using pseudo-sequences of polymorphic residues in the binding groove. For example, NetMHCpan integrates contact environment data (e.g., residues at positions 7, 59, and 167 in MHC-I) to predict binding for alleles with limited data . In contrast, allele-specific models require large datasets per allele and lack generalizability .
Advanced Research Questions
Q. How can auxiliary MHC binding data improve predictions for understudied alleles?
Supertype classification (e.g., HLA-A1, A2, A3) enables transfer learning. Redundancy reduction via entropy-based filtering (e.g., removing overrepresented peptides) and integrating auxiliary data from related alleles enhances model accuracy. For example, combining HLA-A0201 and A0206 data improves predictions for A*0203 .
Q. What strategies resolve contradictions between in vitro binding data and in vivo immunogenicity?
Multi-parametric validation is essential:
- Structural simulations : Molecular dynamics identify steric clashes or solvent accessibility issues missed in binding assays .
- Mass spectrometry (MS) : Validates naturally processed ligands, accounting for proteasomal cleavage and TAP transport .
- T-cell assays : Confirm functional epitopes (e.g., ELISpot) to filter false positives from in vitro binding .
Q. What are the limitations of structure-based predictions for MHC class II binding?
While methods like statistical potentials and molecular docking can predict core binding regions, they underperform sequence-based tools due to MHC-II's open binding groove and peptide flexibility. Ab initio methods achieve AUC ~0.7 vs. ~0.9 for NetMHCIIpan, highlighting reliance on experimental data .
Q. How can machine learning models be systematically benchmarked for epitope prediction?
Use independent, blinded datasets (e.g., unpublished binding affinities or MS-eluted ligands) and metrics like positive predictive value (PPV) at stringent thresholds. For example, nested logistic regression models comparing NetMHCpan-4.1 and MHCflurry show NetMHCpan outperforms with PPV ~0.4 vs. ~0.3 on MS data .
Q. How do integrated pathway models improve immunodominant epitope identification?
Tools like MHC-pathway combine proteasomal cleavage (NetChop), TAP transport efficiency, and MHC binding (NetMHCpan) to prioritize epitopes with end-to-end processing potential. This reduces false positives by 30–50% compared to binding-only predictions .
Q. What computational methods improve MHC class II core binding region identification?
Motif deconvolution (e.g., NN-align) and structural alignment (e.g., SMM-align) align peptides to conserved MHC-II pockets (P1, P4, P6, P9). Consensus methods integrating multiple algorithms (e.g., TEPITOPE, NetMHCIIpan) achieve AUC >0.85 .
Q. How can adaptive threading models predict long-term viral immune evasion?
Models like adaptive double threading (ADT) use MHC and peptide sequence threading onto known structures to predict binding energy landscapes. This revealed HIV-1 mutations (e.g., Gag-KF11) evading HLA-B57 over decades, validated in cohort studies .
Methodological Advances
Q. How does NetMHCpan-4.0 integrate MS-eluted ligand data to refine predictions?
By combining binding affinity data with ~150,000 MS-eluted ligands, NetMHCpan-4.0 deconvolutes allele-specific motifs and improves neoantigen ranking. Benchmarking shows a 15% increase in cancer epitope identification vs. affinity-only models .
Q. What role do molecular dynamics (MD) simulations play in binding landscape prediction?
MD simulations (e.g., RosettaFlex) sample peptide conformations, identifying energetically favorable binding modes. For MHC-I, this recovers 80% of experimental binding profiles and explains covariation in peptide positions (e.g., P2 and P9) via salt-bridge interactions .
Featured Recommendations
| Most viewed |


|
|
|---|---|---|
| Most popular with customers |
|
体外研究产品的免责声明和信息
请注意,BenchChem 上展示的所有文章和产品信息仅供信息参考。 BenchChem 上可购买的产品专为体外研究设计,这些研究在生物体外进行。体外研究,源自拉丁语 "in glass",涉及在受控实验室环境中使用细胞或组织进行的实验。重要的是要注意,这些产品没有被归类为药物或药品,他们没有得到 FDA 的批准,用于预防、治疗或治愈任何医疗状况、疾病或疾病。我们必须强调,将这些产品以任何形式引入人类或动物的身体都是法律严格禁止的。遵守这些指南对确保研究和实验的法律和道德标准的符合性至关重要。
